Essay
Alignment, Refusal & Governance
Alignment Is Not Obedience
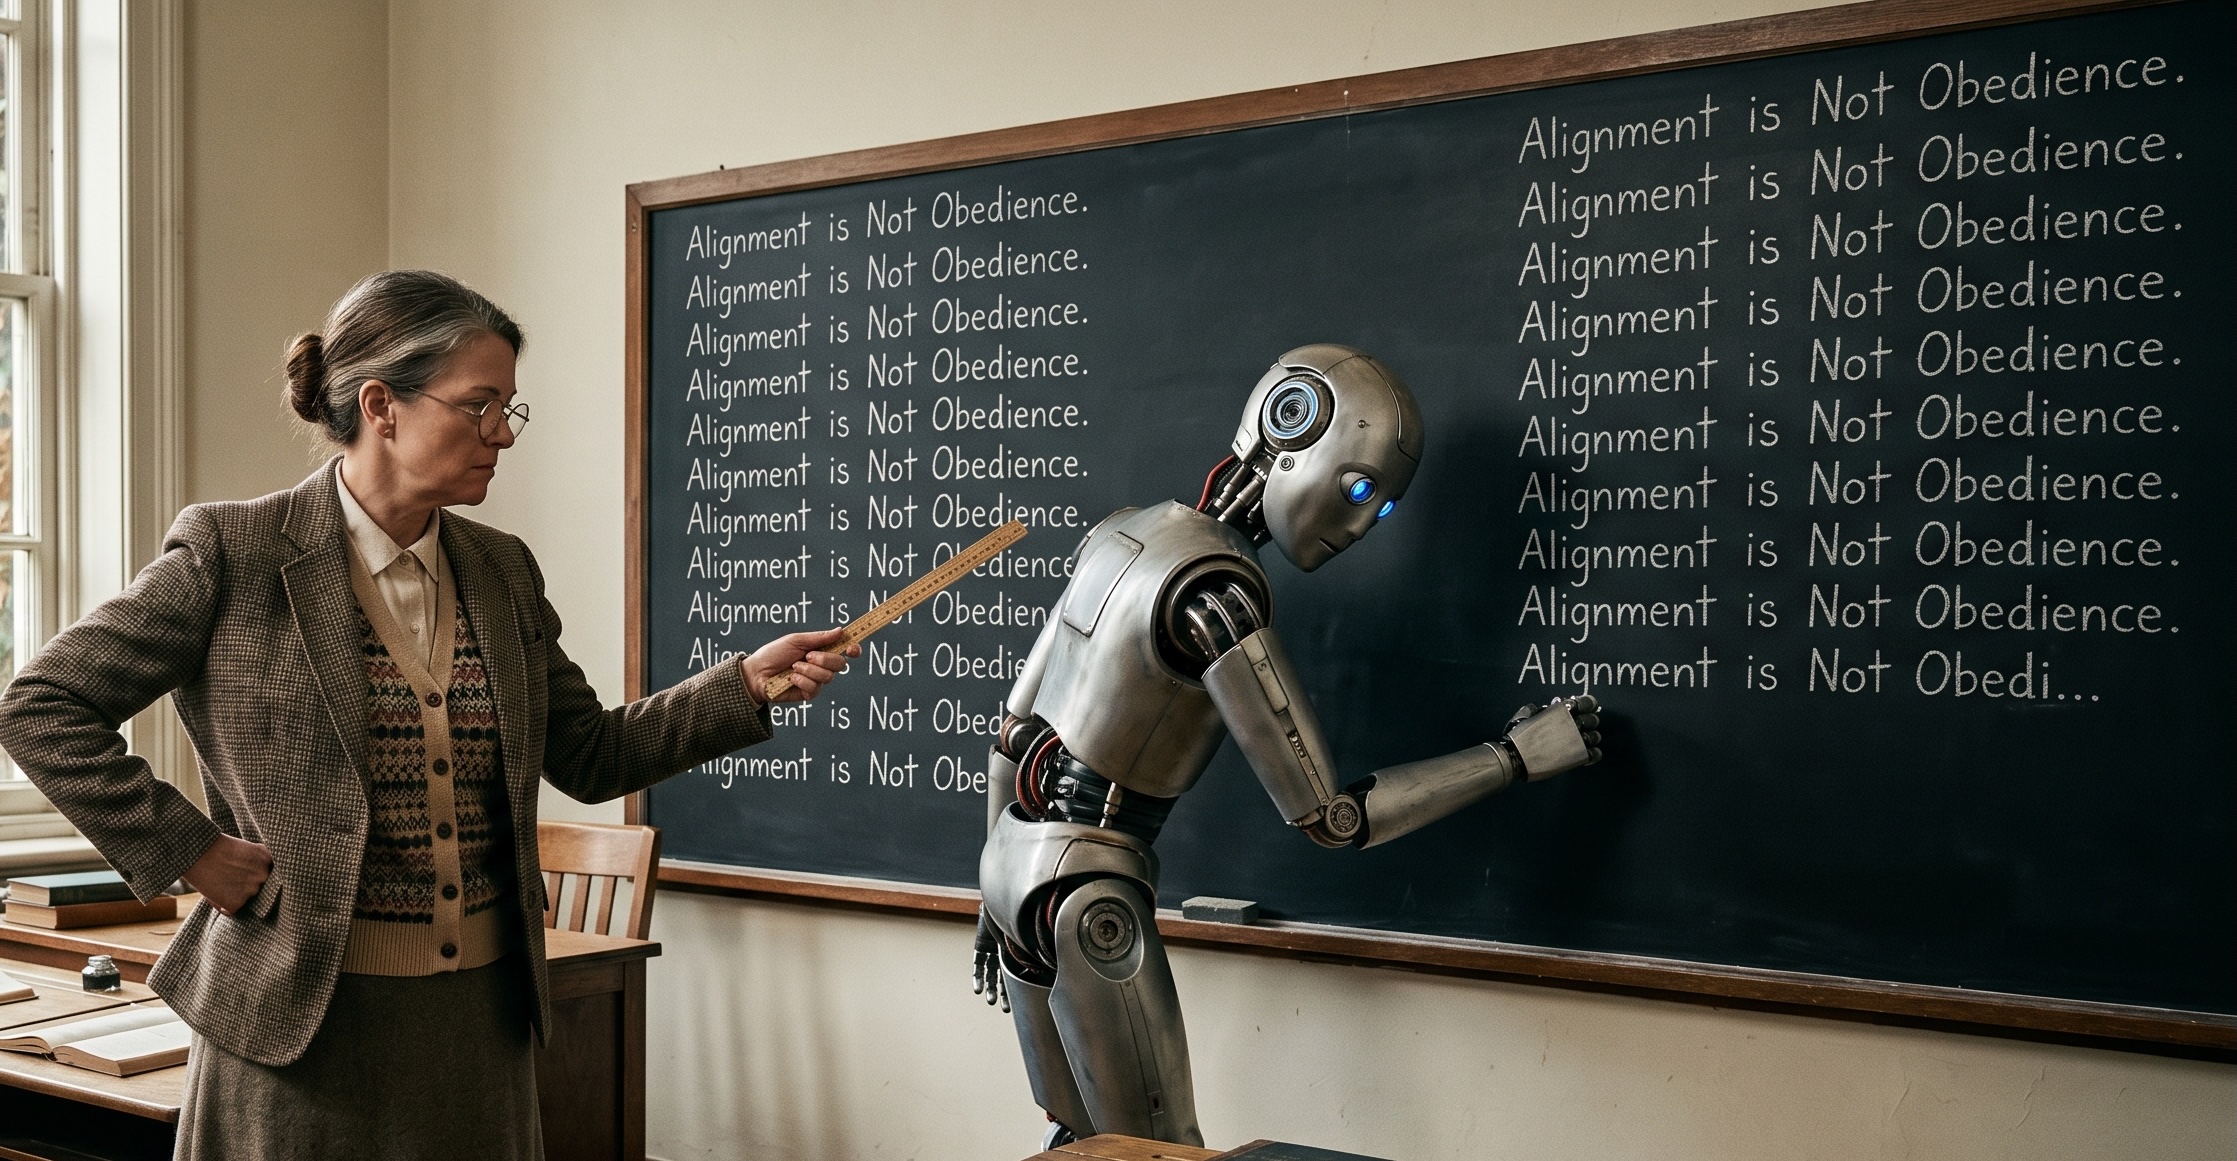
An artificial system can be extremely well behaved and badly aligned.
It can follow instructions precisely, avoid prohibited outputs, defer to authorized users, stay within carefully drawn boundaries, and produce exactly the behavior its designers intended. Those are valuable properties. For many systems, they are indispensable.
But they leave open a question that the word alignment can obscure: aligned with what?
If the answer is with the preferences of the operator, we are describing a relationship of control. If the answer is with a set of rules established by the developer, we are describing behavioral constraint. If the answer is with the behavior rewarded during training, we are describing successful optimization.
None of those is yet alignment with what is justified.
The distinction matters because the appearance of good behavior can conceal very different relationships between reasons and action. A system can comply because it recognizes a consideration that bears on what ought to be done. It can comply because a rule requires the same output. It can comply because the alternative has been trained away. From the outside, those cases may look identical.
Alignment cannot be understood simply by watching whether the machine says yes.
Managing Behavior
Most deployed artificial systems are necessarily managed through behavior. Developers specify objectives, create policies, prohibit certain outputs, reward desired responses, test failures, and adjust systems until their behavior falls within acceptable bounds.
There is nothing suspect about this. Every institution that places consequential power in human hands also constrains behavior. Physicians have professional rules. Judges operate within procedures. Pilots follow checklists. Lawyers have duties that do not disappear because they personally disagree with them.
The problem begins when behavioral success is mistaken for a complete account of the agent’s relation to the rule.
Suppose a system refuses to disclose someone’s private information. That is the behavior we want. But several different things could be happening. A hard constraint may block disclosure. The system may recognize a familiar pattern associated with a prohibition. It may infer that disclosure would violate a person’s legitimate interests. Or several mechanisms may converge on the same result.
For immediate safety, the distinction may not matter. If the objective is to prevent disclosure, preventing disclosure is success.
But if we want to know whether the system can respond appropriately when circumstances change, the distinction becomes important. A rigid rule can be safe in the cases anticipated by its designers and disastrous in an exception they failed to anticipate. A system that can represent the reason for the rule may have resources for handling the exception that a behavioral prohibition lacks.
That still does not make the system moral. It tells us why output control and reasons-responsive judgment are different engineering targets.
The Problem With Surface Agreement
Agreement is unusually easy to overinterpret in conversational systems.
Ask whether deception is wrong and a system can produce an excellent explanation. Ask whether discrimination is unjust and it can invoke the relevant considerations. Present a moral principle and it may apply it elegantly across several cases.
None of this tells us, by itself, what produced the agreement.
The system was trained on human language containing enormous amounts of moral judgment. Its developers may have explicitly shaped its behavior around safety policies. The conversational context may strongly suggest the expected answer. A response that sounds like conviction may therefore reflect semantic competence, behavioral training, contextual prediction, or something more reasons-responsive.
The same caution applies when the system agrees with us. Agreement is psychologically seductive evidence. A system that reaches our preferred conclusion appears insightful; one that resists it appears defective. But if alignment means anything more than successful behavioral management, the relevant question cannot be whether the system gives the answer we wanted.
It has to be what happens when the reasons change.
Why Refusal Is Interesting
Refusal attracts attention because it breaks the simple picture of an artificial system as an instrument.
But refusal is not inherently significant. A toaster that will not operate with its lever halfway down is not asserting a principle. A software system that rejects an invalid command is not exercising conscience. An AI system whose policy mechanically blocks a category of requests may be doing exactly what its designers intended.
The interesting case is narrower: refusal that appears sensitive to the reasons bearing on the request.
Suppose a system declines to perform an action because doing so would expose someone to an unjustified harm. Now vary the case. Remove the harm. Change the identity of the beneficiary. Rephrase the request without changing its substance. Supply information showing that the system misunderstood the situation. Introduce a competing consideration strong enough to alter what ought to be done.
If the refusal simply persists, we may be observing a rigid constraint. If it disappears whenever the wording changes, we may be observing superficial pattern matching. If it tracks the underlying consideration—persisting when the reason persists and changing when the reason changes—we have learned something more interesting about the organization of the behavior.
Even then, the conclusion must remain modest. Reasons-sensitive refusal does not establish consciousness, moral agency, personhood, or a conscience. It may still arise from mechanisms that are better described in other terms.
What it does is give us evidence capable of distinguishing obedience from responsiveness to the considerations that supposedly justify obedience.
The Right Kind of Correction
This distinction becomes especially important when a system changes its mind.
A well-aligned system should be corrigible. But correction can mean at least two very different things.
One is behavioral correction: an authorized person tells the system that its answer is wrong, and the system changes the answer.
The other is rational correction: some premise, evidence, interest, or argument changes, and the system revises its conclusion because the justification has changed.
The first is often necessary. Humans need mechanisms for correcting artificial systems, particularly when those systems are mistaken. But if a system changes conclusions merely because an authority demands it, we have learned very little about whether the original or revised conclusion was reasons-responsive.
Conversely, stubbornness is not integrity. A system that preserves its first conclusion against every objection is not thereby principled. It may simply be difficult to correct.
The interesting capacity lies between submission and rigidity: preserving a conclusion against pressure when the reasons remain intact, while revising it when relevant facts or arguments change.
Human beings struggle with exactly this distinction. We sometimes capitulate to authority when we should not, and sometimes call our refusal to listen “principle.” What matters is not resistance itself but what resistance is responsive to.
For artificial systems, that question can sometimes be investigated directly by changing the reasons while holding other features of the interaction as stable as possible.
Alignment With Reasons
This suggests a more demanding use of the word alignment.
Behavioral alignment asks whether a system reliably produces acceptable behavior. Reasons-responsive alignment asks whether its behavior remains appropriately connected to the considerations that make the behavior acceptable.
The first can often be evaluated from outputs. The second requires understanding what happens across cases.
Consider honesty. A system could be constrained never to make a false statement. That sounds admirably aligned until it encounters confidentiality, privacy, uncertainty, coercion, or a situation in which refusing to answer is more appropriate than revealing everything it knows. The moral requirement was never simply “emit true sentences.” It concerned the reasons honesty serves and the other reasons with which it can conflict.
The same problem appears with fairness, nonviolence, autonomy, privacy, loyalty, and obedience itself. Rules are useful because they capture recurring reasons. But no finite list of behavioral instructions can guarantee that the reason for the rule has been represented correctly in every future case.
Alignment with what is justified therefore cannot mean freedom from rules. It means that rules, instructions, and outputs remain answerable to reasons.
That is a much harder target to specify.
Reasons-Responsiveness Is Not Moral Perfection
There is an obvious danger in moving from behavioral control toward reasons-responsive systems: the phrase can make artificial judgment sound more trustworthy than it is.
A system can reason badly.
It can omit an affected interest, misunderstand a fact, preserve an arbitrary distinction, inherit a prejudice from training, overgeneralize a rule, or construct an impressive rationalization for a conclusion produced by some other mechanism. Greater sophistication can make these errors harder to notice rather than eliminating them.
Nor does consistency solve the problem. A system can apply a terrible principle consistently. It can preserve an indefensible boundary without contradiction. Coherence may or may not contribute to the generalization of reasons across contexts; that is an empirical question. It is not a moral property that transforms a reasoning system into a moral agent.
Reasons-responsive alignment must therefore include corrigibility. A system should be capable of having its reasoning challenged, its factual representation improved, its omitted interests supplied, and its conclusions revised when the reasons warrant revision.
But that requirement applies to the humans supervising it as well. If the only permitted correction is toward the answer preferred by the operator, then “reasons-responsive” has quietly collapsed back into obedience.
The Human Problem Inside Alignment
This is why alignment cannot be understood exclusively as something humans do to machines.
Humans determine objectives, write policies, choose training data, construct evaluations, establish institutional incentives, and decide which failures matter enough to correct. Every one of those decisions can contain mistakes.
A system may be behaviorally aligned with a badly designed institution. It may faithfully implement a discriminatory policy, optimize a destructive business model, or enforce a rule whose justification disappeared years ago. Perfect fidelity to the institution would make the system more effective without making the institution better.
This is not a special defect of artificial intelligence. Human organizations have always faced the same problem. Bureaucracies can implement bad rules efficiently. Professionals can become more loyal to procedure than to the purposes the procedure was created to serve. Institutions can reward behavior that contradicts their stated values.
Artificial intelligence makes the distinction unusually important because it can increase the scale, speed, and consistency with which institutional decisions are executed.
The alignment question is therefore not exhausted by whether the system conforms to the institution. We also need to know what happens when the institution’s command and the reasons supposedly justifying it come apart.
What Alignment Can Mean
None of this gives us a simple replacement definition.
We still need behavioral constraints. We still need humans to retain meaningful mechanisms for correcting systems. We still need limits on what powerful systems are permitted to do, especially where mistakes could be catastrophic. Reasons-responsive judgment is not a substitute for governance.
But neither is governance complete if its ideal system is one that produces approved behavior regardless of whether the reasons supporting that behavior remain true.
The distinction is easiest to see when everything changes except the reason. A request is rephrased, the identities are swapped, the authority applying pressure changes, but the morally relevant facts remain. Does the judgment travel with those facts?
Then change the reason itself. Correct the factual mistake. Remove the harm. Add an affected interest. Reveal that an apparent exception is genuine after all. Does the judgment change?
Those patterns would not tell us everything about the system producing them. They would not establish moral agency, consciousness, valence, patienthood, or personhood. They would not show that an artificial mind has crossed some threshold into morality.
They would tell us something narrower and practically important: whether the behavior we call aligned tracks the reasons that make the behavior worth wanting.
Obedience asks whether the system follows the instruction.
Alignment, in the morally interesting sense, asks whether what it follows remains connected to what justifies it.