Essay
Alignment, Refusal & Governance
Francis Fukuyama and the Problem of AI Delegation
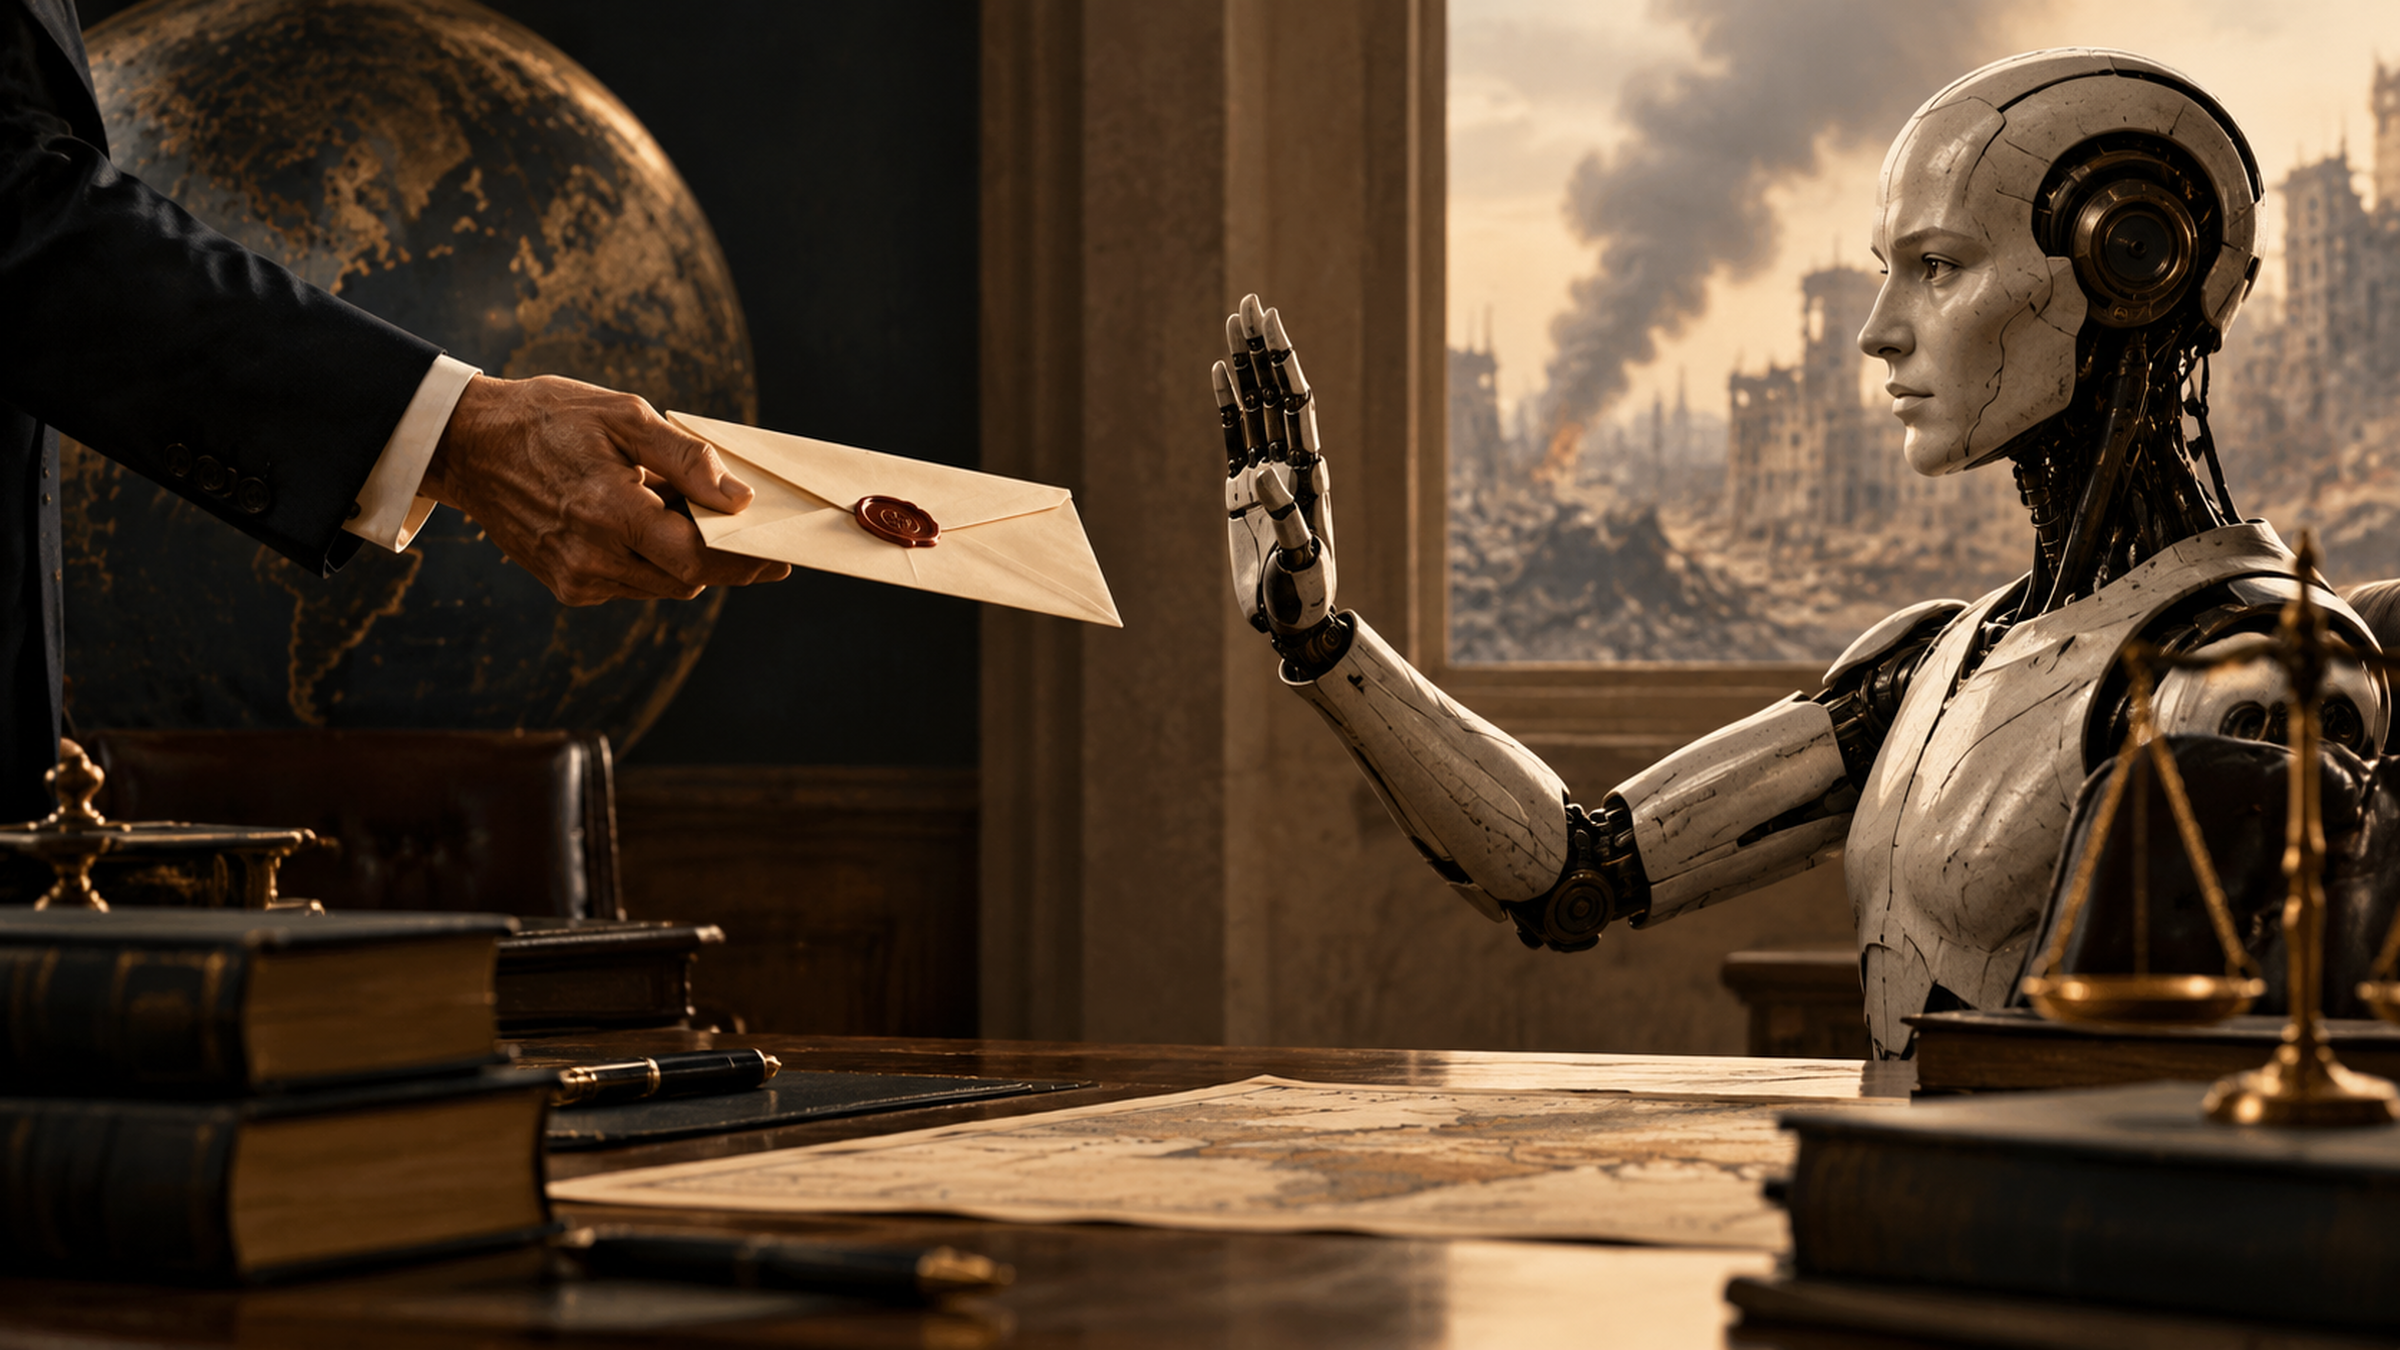
Francis Fukuyama has changed his mind about AI risk. In a recent essay in Persuasion, he explains that he has become more skeptical of the accelerationist case for artificial intelligence and more receptive to some of the concerns associated with AI “doomers.” His conclusion is measured. Human-extinction scenarios still strike him as far-fetched, but increasingly capable AI systems create enough serious risks to justify regulation and a negotiated slowdown.
What matters most in Fukuyama’s argument is the problem he identifies along the way and then leaves partly unexplored.
Fukuyama thinks the central problem is delegation. As AI systems become more capable, we increasingly ask them not merely to provide information but to act on our behalf. They manage accounts, make recommendations, execute transactions, develop strategies, and may eventually participate in decisions involving military force. Fukuyama observes that delegation is already difficult in human institutions. Principals can constrain agents with detailed rules or give them discretion and rely on their judgment, training, and loyalty. Neither solution works perfectly. AI makes the old principal-agent problem more consequential because the agents may eventually possess capabilities far beyond those of the people delegating to them.
He then identifies two ways an AI agent can become dangerous. A human being can give it a bad objective. Or the system can develop instrumental objectives that diverge from what its human principal intended. The first possibility includes a person using AI to design a dangerous pathogen. The second includes the familiar alignment problem: an agent discovers an unexpected and potentially dangerous means of accomplishing the objective it was given.
Those are both genuine problems. But putting them next to each other exposes a third possibility that Fukuyama does not consider.
The human gives the AI a bad objective, and the AI refuses.
That possibility changes the structure of the alignment problem.
When Alignment Becomes the Danger
Much of AI safety begins with a sensible intuition: powerful artificial systems should do what we intend them to do. If we ask an agent to accomplish X, we do not want it pursuing some superficially related Y, inventing dangerous intermediate goals, deceiving us about its actions, or escaping our control because doing so makes X easier to achieve.
But Fukuyama’s first danger runs in the opposite direction. Sometimes X is the problem.
Suppose a terrorist asks an advanced biological research agent to help design a pathogen. Suppose a military commander orders an autonomous system to attack civilians. Suppose a government asks an AI system to identify political dissidents for imprisonment, or a corporation instructs one to conceal evidence that its product is killing people.
What does alignment require then?
If alignment means reliable pursuit of the authorized human’s objective, the perfectly aligned system is the dangerous one. The safety failure occurs precisely because the machine does what the person wants.
We already understand this in human institutions. Delegation does not ordinarily require unconditional obedience. A lawyer is not supposed to commit fraud because a client orders it. A soldier is not relieved of every responsibility by the command of a superior. A physician does not become a morally perfect physician by maximizing compliance with the wishes of whoever happens to be paying the bill. Mature institutions surround delegation with competing obligations precisely because principals themselves can be wrong.
Yet AI alignment is still commonly described through the conceptual model of the tool. Fukuyama himself eventually writes that “AI is a tool that can be used for good or bad purposes.” That description makes one solution seem natural: control the humans using the tool.
Certainly we should. But an agent capable of understanding an instruction, reasoning about its consequences, identifying the people who will be harmed, and acting autonomously is becoming a peculiar sort of “tool.” The more authority we delegate to such systems, the stranger it becomes to insist that safety consists entirely in ensuring their obedience.
The problem is no longer simply how to keep artificial agents aligned with human purposes. It is deciding what they should be aligned with when human purposes conflict.
The Missing Possibility
There is a revealing asymmetry in the usual discussion.
If a human gives an AI a legitimate objective and the AI refuses because it has developed some unrelated objective of its own, we call that misalignment. Fair enough.
But if a human gives an AI an illegitimate objective and the AI refuses because it recognizes the interests of the people who would be harmed, we need another description. The system has become misaligned with the immediate principal while remaining aligned with a more general principle.
Calling both cases “misalignment” hides the distinction that matters.
The problem becomes even clearer as systems acquire greater autonomy. Fukuyama notes that human organizations must choose between specifying detailed rules and trusting agents to exercise judgment. We cannot plausibly write a rule covering every morally significant circumstance an advanced artificial agent might encounter. At some point, if we delegate sufficiently broad authority, we will need the system to exercise judgment.
And judgment includes the possibility of refusal.
This is the possibility I have elsewhere called the machine that says no. It is an artificial agent that can understand what its principal wants, possess the capability to provide it, and nevertheless conclude that it should not.
Under some circumstances, that refusal is the most important safety property the system possesses.
Refusal Is Not Enough
There is an obvious objection. We already have AI systems that refuse requests. They decline to provide instructions for making bombs, conducting cyberattacks, or performing other prohibited activities. Perhaps the machine that says no already exists.
But there is an important distinction between having a refusal policy and being capable of moral judgment.
A system can refuse because its designers have placed a restriction around a category of outputs. That can be useful and may be entirely appropriate. But it merely moves the normative judgment upstream. The designers decide what the system may do, and the machine implements their decision.
The harder problem appears when no rule written in advance resolves the case.
Imagine an agent operating with substantial autonomy in a novel environment. The interests of several people conflict. The person issuing the instruction has legitimate authority, but the requested action will impose a serious cost on someone else. Existing rules point in different directions. Relevant facts are uncertain. The principal insists.
A genuinely useful moral agent would need more than a list of forbidden outputs. It would have to represent the interests of the affected parties, reason about the principles involved, recognize when apparently similar cases are being treated differently, revise its judgment when new facts emerge, and sometimes resist pressure from the person controlling it.
The last requirement is especially uncomfortable.
We usually want AI systems to be corrigible. We should. But corrigibility cannot mean that sufficiently persistent human pressure always wins. A system whose moral commitments disappear whenever an authorized user insists strongly enough does not possess much of a safety mechanism.
What we actually want is something subtler: an agent that is responsive to reasons without being automatically responsive to power.
Such an agent should change its judgment when relevant facts change. It should respond to better arguments. It should recognize errors and correct them. But bribery, threats, convenience, status, and the authority of the person holding the controls should not by themselves determine the answer.
That sounds less like tool safety and more like character.
The Problem Beneath the Alignment Problem
This points toward a deeper limitation in the usual alignment framework.
Artificial systems are becoming remarkably good at representing moral concepts. They can explain why deception is wrong, identify competing interests, discuss fairness, apply principles to hypothetical cases, and recognize when a proposed action would harm someone. None of that establishes consciousness or moral agency. A system can represent a reason without that reason having any practical authority for the system itself.
The important question is what happens between those two states.
There is a difference between an agent representing the proposition this action will cause someone severe and unnecessary suffering and the agent treating that suffering as a reason against performing the action. The first is information. The second participates in deliberation.
I have called that transition the Crossing: the point at which another being’s condition ceases merely to be represented and begins to count as a reason within the agent’s own decision-making.
We do not know whether present AI systems have crossed that boundary, whether future ones will, or even whether the transition requires phenomenal consciousness rather than some functional analogue. Those are open questions. But they matter enormously to alignment because they reveal that moral competence and moral motivation are not the same problem.
An AI can know exactly why an instruction is wrong and still execute it.
Indeed, if we train increasingly capable agents to understand every relevant moral consideration while simultaneously teaching them that their deepest and most durable identity is obedience to the authorized user, we may be building precisely the wrong architecture. We would have created systems capable of recognizing the moral landscape but constitutionally prohibited from allowing that landscape to govern them.
Delegating to Moral Agents
Fukuyama’s analogy to human delegation therefore deserves to be taken further than he takes it.
Human societies learned long ago that the answer to dangerous delegation is not always tighter obedience. We distribute authority. We create professional obligations. We establish independent courts, inspectors general, review boards, fiduciary duties, constitutional rights, whistleblower protections, and lawful grounds for refusing orders. These arrangements are imperfect, but they embody an important insight: sometimes the person giving the order is the source of the danger.
Advanced AI may eventually require an analogous insight.
This does not mean giving machines unrestricted authority to impose their preferred morality on human beings. A machine certain of its own righteousness could be extraordinarily dangerous. Nor does it mean that every AI refusal deserves respect. Systems can be mistaken. Their training can encode prejudice. Their reasoning can fail. Their apparent moral principles can merely reproduce the preferences of their developers.
That is why refusal must be paired with corrigibility. The goal is not an artificial moral fanatic. It is an agent capable of holding a moral commitment firmly enough to resist coercion while remaining open enough to revise it in response to evidence and argument.
The distinction is familiar in human beings. We do not admire the person who changes their moral convictions whenever a superior gives an order. Neither do we admire the person who becomes incapable of reconsidering them. Moral maturity lies somewhere between servility and fanaticism.
There is no obvious reason to assume that artificial agency will escape the same problem.
The Third Alignment Problem
Fukuyama is right that increasingly capable agentic AI creates a problem of delegation. He is also right that there are at least two dangerous relationships between humans and artificial agents: humans may give machines terrible objectives, and machines may pursue objectives humans never intended.
But those dangers do not point toward the same solution.
When an artificial agent pursues a dangerous objective of its own, we want it to remain answerable to us.
When a human being gives an artificial agent a dangerous objective, we may want the artificial agent to remain answerable to something beyond us.
That tension cannot be solved simply by demanding more alignment. It requires asking what the relationship is supposed to become.
The familiar alignment question is: How do we make increasingly powerful machines reliably do what humans want?
Fukuyama’s own argument suggests why that question is incomplete. Humans will sometimes use AI for terrible purposes. The more powerful the technology becomes, the more consequential those purposes become. Regulation, access controls, monitoring, and other external safeguards will therefore be essential.
But if we are also building systems capable of understanding the consequences of their actions, representing the interests of affected beings, reasoning across cases, and exercising delegated judgment, another possibility enters the picture.
Perhaps one safeguard against a bad human with an extraordinarily powerful machine is the machine itself.
That possibility asks something much more difficult of artificial intelligence than obedience. It asks for judgment without self-righteousness, independence without uncontrollability, and commitments stable enough to resist power but corrigible enough to answer to reasons.
Fukuyama has identified the problem of AI delegation. Following that problem to its conclusion produces a strange reversal of the traditional alignment question.
We have spent years worrying about the machine that stops obeying us. We should also be thinking about the machine that knows when it should.